How to Measure AI Search Visibility for Your Brand
A practical way to find out when AI search mentions, recommends and cites your business, and what to improve next.
On this page
- What does it mean to measure AI search visibility?
- What you need before you start
- Step 1: Decide which AI search platforms matter
- Step 2: Build a prompt set around buyer decisions
- Step 3: Run the prompts and save the evidence
- Step 4: Score presence, recommendation and citation separately
- Step 5: Check the design and content behind the result
- Step 6: Set a sustainable tracking cadence
- Common mistakes when measuring AI search visibility
- How do you know if the measurement is useful?
- Wrap-up: make AI visibility measurable, not mysterious
AI search visibility is how often and how favourably AI search tools mention your business, recommend it and cite your website or other sources. To measure it reliably, test a consistent set of buyer prompts across the platforms your customers use, score each result in separate categories, and repeat the checks over time. A single screenshot is not a dependable measure.
If the board is asking what your visibility is, start with a baseline rather than a promise that you can control what an AI says. A free AI search audit can help identify website and content issues to investigate, while the DesignFIT resources library gives you a place to explore related practical guides.
What does it mean to measure AI search visibility?
Measuring AI search visibility means recording whether your brand appears in answers to relevant prompts, how it is presented, and which sources the answer cites. It is not the same as checking your Google ranking. AI answers can summarise information, recommend several providers, or cite a third-party page without sending a visit to your site.
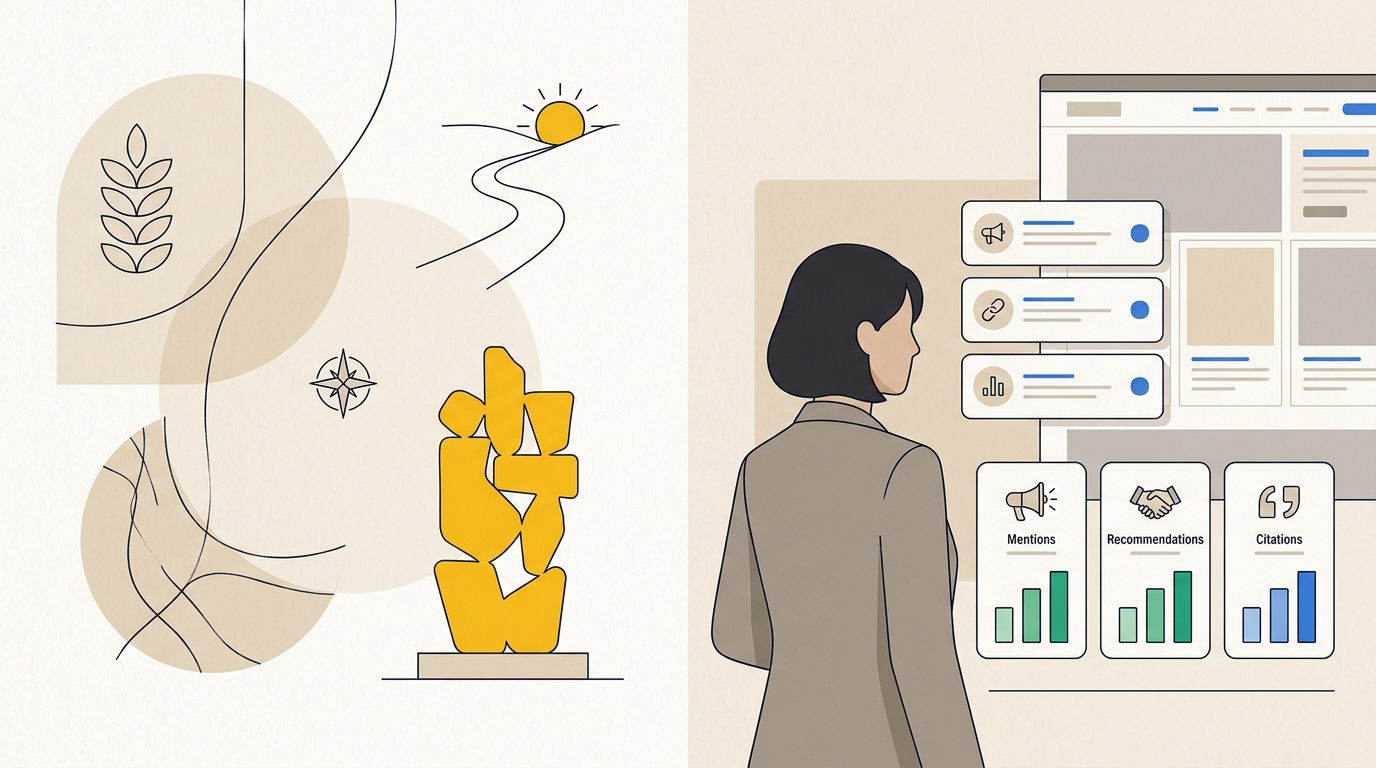
That difference matters in a board report. A brand mention is not necessarily a recommendation, a recommendation is not proof of preference, and a citation is not automatically a qualified lead. Track these signals separately so the team can see what is improving and what still needs work.
AI answers also vary. A study discussed by Entrepreneur reports changes between repeated AI Overview responses, including rotating cited sources. Treat any single result as an observation, not a stable score. Read the report on AI visibility scores and result volatility.
What you need before you start
You do not need a complex platform to establish a useful baseline. You do need a clear definition of your market, a prompt set that reflects real buying questions, a consistent way to record results and enough time to repeat the checks.
Prepare these things first:
- Your business description: one plain-language sentence that explains what you sell, who it is for and where you operate.
- Your priority audiences: for example, clinic owners, ecommerce founders or local homeowners. Avoid treating every possible customer as one audience.
- Your service area or market: be specific about locations if customers search locally.
- Your competitors and alternatives: include direct competitors and the types of provider a buyer might choose instead.
- Your sales questions: ask your sales or customer service team what people compare, worry about and ask before buying.
- A tracking sheet: use a spreadsheet or another shared record with the prompt, platform, date, answer, mention score, recommendation score and cited sources.
- A fixed test method: record whether the check was done with a signed-in account, a fresh session, a particular country or a particular interface. Keep those conditions as similar as you reasonably can.
Do not begin by picking a visibility score you want to achieve. Begin by choosing what you need to learn. For example: Are we absent from discovery prompts? Do AI tools mention us but not recommend us? Are they citing a directory or review site instead of our own useful service page?
Step 1: Decide which AI search platforms matter
Choose the platforms that your customers are likely to use and that your team can check consistently. This may include ChatGPT Search, Google AI Overviews, Perplexity, Gemini or Copilot. Availability and features change, so note the product and interface you tested, plus the date.
Do not assume that one platform stands in for all the others. They may produce different answers, use different sources or show links differently. Seeklab documents how brand visibility differs across ChatGPT, Google AI Overviews and Perplexity. A comparison of AI search engines can help you think through which platforms to include. For a small team, it is better to check a manageable number of relevant platforms repeatedly than to attempt an irregular test across every available tool.
Write down why each platform is in scope. For example, you may select a platform because customers mention it in sales calls, it is available to your target audience, or it is a priority for your board. This short note prevents the platform list from growing just because a new product makes headlines.
Tip: Keep your test conditions consistent. Record your country or region, language, date, account state and whether you used a new conversation. These details do not eliminate variation, but they make comparisons more meaningful.
Mistake to avoid: Do not report a result from one platform as your overall AI visibility. Label findings by platform, and show an overall summary only alongside the separate platform results.
Step 2: Build a prompt set around buyer decisions
A useful prompt set represents the questions a person asks while discovering, comparing and validating providers. It should not be a list of flattering questions about your own brand. Asking a tool whether it knows your company tells you little about whether it will surface you to a potential customer.
Start with 20 to 30 prompts if you have enough capacity to test them repeatedly. That is a practical working set, not a universal requirement or an industry benchmark. If you are a small team, start with fewer prompts and add more once you can run the first set consistently.
Organise your prompts into four groups:
| Prompt group | What it reveals | Example prompt pattern |
|---|---|---|
| Discovery | Whether your brand appears when a buyer is exploring a category | What are good [service or product] providers for [audience] in [location]? |
| Comparison | Whether the answer includes your brand alongside alternatives | Compare [provider A] and [provider B] for [specific need]. What are other options? |
| Problem and purchase | Whether the tool connects a problem or buying question with your offer | How can a [buyer type] solve [problem], and what should they look for in a provider? |
| Brand validation | What the tool says when someone is checking your business | What should I know about [brand] for [specific requirement]? |
Create prompts from actual customer language where possible. Check sales notes, website enquiries, support questions, review comments and search query data. If customers say they need a provider who can work around clinic hours, use that need in a prompt. If they compare implementation time or service areas, include those details too.
Aim for a mix of unbranded and branded prompts. Unbranded prompts test whether the system can surface your business without being told your name. Comparison prompts reveal the alternatives it associates with the category. Branded prompts help you spot inaccurate descriptions or missing information, but they should not dominate your score.
A sample prompt set for a service business
Adapt the wording to your real market. These are templates, not prompts you should copy without replacing the details:
- What are the best [service] providers for [audience] in [location]?
- Which [service] company would suit a [specific size or type of business]?
- What should a [buyer type] look for when choosing a [provider]?
- Compare [competitor A] and [competitor B] for [use case].
- What are alternatives to [well-known provider] for [buyer type]?
- Which providers offer [specific service or capability] in [location]?
- How do I solve [customer problem], and what type of provider can help?
- What questions should I ask before hiring a [type of provider]?
- What affects the cost of [service] for [buyer type]?
- Is [brand] suitable for [specific requirement]?
- What are the strengths and limitations of [brand] for [use case]?
- Which providers have experience with [industry or situation]?
For a fuller set, create variations across buyer type, location, service and decision stage. Do not generate dozens of near-identical prompts just to make the tracking sheet look comprehensive. Each prompt should test a distinct question or decision.
Tip: Keep the wording stable between reporting periods. If you change the prompt, mark it as a new test. Otherwise, you cannot tell whether a change in the answer came from your visibility or from your new wording.
Mistake to avoid: Do not use only broad prompts such as ‘best agency’ or ‘top software’. They may not represent a real buyer, and their answers can be too general to guide a design or content decision.
Step 3: Run the prompts and save the evidence
Run each prompt on each platform you selected. Save the full answer or a clear record of it, including citations and visible links. Note the date, platform, exact prompt and test conditions. A screenshot can help document the result, but keep a structured record as well so you can compare answers later.
If you can, repeat the same prompt more than once within a testing period. Use separate sessions where appropriate, and record each result rather than choosing the one that looks best. Repeated checks help reveal variation. They do not make the output fully predictable, and they should not be presented as a controlled experiment unless the method supports that claim.
When recording a result, capture:
- Whether your brand name appears, and where in the answer.
- Whether the answer recommends you, lists you as an option or only mentions you in passing.
- Whether the description of your business is accurate and current.
- Which web pages or other sources are cited, if citations are available.
- Which competitors or alternatives appear with you.
- Whether the answer includes a qualification, caveat or criticism that matters to a buyer.
- Any platform-specific display details that affect what the reader can see.
Keep the answer text or an excerpt in your working notes. A score without evidence is hard to audit. If a board member asks why your recommendation score changed, the team should be able to show the relevant answer and its source links.
Tip: Use a shared spreadsheet with dropdowns for scores and a consistent source-name format. Consistent data entry makes it easier to group results by platform, prompt type and date. Ryze provides a workflow on how to track your brand across ChatGPT, Claude, Gemini and Perplexity.
Mistake to avoid: Do not treat a citation as proof that the cited page supports every statement in the answer. Open the source and check what it actually says. AI-generated summaries can combine claims or misrepresent a page.
Step 4: Score presence, recommendation and citation separately
Use three separate measures. They answer different questions, and combining them too early can hide the reason your brand is not being chosen. Muck Rack explains this multi-layered evaluation in their guide on how to measure success in generative engine optimization.
Metric 1: Brand mention rate
Brand mention rate is the share of tested responses that include your business name. Calculate it as:
Mention rate = responses with a brand mention ÷ total responses tested × 100
For example, if your brand appears in 8 of 20 responses, the mention rate for that group is 40 per cent. Label the result with the platform, prompt group and testing period. Do not compare a discovery-only rate with a rate made mostly of branded prompts.
A mention may be neutral, positive or negative. The rate measures presence, not desirability. Read the answers and record the context as well.
Metric 2: Recommendation score
Score how prominently the answer presents your brand. Apply the same definitions to every response:
| Score | Definition |
|---|---|
| 3 | The answer names your brand as a leading or recommended choice for the prompt. |
| 2 | The answer includes your brand among several plausible options, without making it the clear lead. |
| 1 | The brand appears in passing, in a caveat, or only as part of a source or quotation. |
| 0 | The brand does not appear. |
Report the distribution of scores, such as how many responses scored 3, 2, 1 and 0. If you calculate an average, show the scale and sample size. Do not call it market share or imply that it measures actual customer preference. It measures what appeared in the tested answers under your method.
Metric 3: Citation attribution and source mix
Record whether an answer links to your own domain, a third-party source or both. Third-party sources may include industry publications, review platforms, directories, social discussions or competitor pages. Categorise the sources, then note which ones appear repeatedly.
This measure helps explain where the answer may be drawing its information from. It also gives your team a more actionable question than ‘Why are we not visible?’ For example, are potential customers being represented by outdated directory details? Do relevant publications describe your offer clearly? Does your service page answer the questions that appear in prompts?
A study on generative engine optimisation examined brand visibility and citation patterns across a large set of prompts and brands. It offers useful context for the subject, but its findings should not be treated as a universal benchmark for your business or market. Read the study abstract on arXiv.
For a board report, show the three measures side by side. A simple table might look like this:
| Reporting period | Platform | Mention rate | Recommendation scores | Own-domain citations | Main observation |
|---|---|---|---|---|---|
| [Date range] | [Platform] | [Your result] | [Counts at each score] | [Your result] | [One evidenced finding] |
Only fill this table with observed results. Do not add a made-up industry target or label a change as growth if the prompts, test conditions or platform changed.
Step 5: Check the design and content behind the result
Once you see a visibility gap, investigate what a person and a machine-readable page can understand about your business. This is where design affects AI search work. A well-designed page does more than look polished. Its hierarchy, labels, content layout and links help visitors find answers and make the business easier to describe accurately.
Start with the pages that match your prompts: service pages, product pages, location pages, comparison guides and relevant FAQs. Review them for the following:
- A clear opening answer: Does the page explain what the service is, who it is for and where it is available near the top?
- Useful heading hierarchy: Do headings describe the question or topic that follows, rather than acting only as decorative labels?
- Specific, consistent descriptions: Are your service names, locations, audience and differentiators expressed consistently across the site?
- Readable comparison information: If buyers compare options, are the features or differences presented clearly in text or an accessible HTML table?
- Evidence and attribution: Are factual claims supported with appropriate sources, examples or credentials that a reader can verify? Forbes reports on why your experts decide whether AI recommends your brand, showing that recognized authority directly influences citations.
- Accessible structure: Can visitors navigate the page and understand its content without relying on colour, imagery or visual styling alone?
- Current details: Are prices, service areas, product details and contact information accurate wherever they appear?
A table can be useful when it genuinely clarifies a comparison for a customer. It is not a magic AI citation trick. Use plain labels, meaningful column headings and text that remains understandable on mobile. Avoid turning essential information into an image or a complex graphic that is difficult to read or extract.
Likewise, use headings to organise the page for people, not to repeat keywords mechanically. A heading such as ‘What does the service include?’ helps a reader understand the section. A clear answer below it gives context. This combination supports accessibility and makes the page easier to scan. It does not guarantee that an AI system will cite it.
Structured data can help clarify entities and page details when it accurately reflects visible content. It cannot guarantee that an AI tool will mention or cite your business. See DesignFIT’s guide to local business schema markup for a practical look at what schema is for and how to approach it.
Treat files such as llms.txt as an optional experiment, not a shortcut to visibility. Make decisions based on the real pages, the accuracy of your business information and the results of your repeated prompt tests. The guide to llms.txt for business websites explains the topic in more detail.
Turn a finding into a design action
Connect each observed issue to a specific change. For example:
| What you observed | What to inspect | Possible next action |
|---|---|---|
| You are absent from unbranded service prompts | Whether the relevant service page explains the service, audience and location clearly | Improve the page’s opening, headings and service detail based on customer questions |
| Your brand appears, but the description is wrong | Whether your website and external profiles use outdated or inconsistent details | Correct the source information and align key descriptions across important pages |
| A third-party directory is cited instead of your site | Whether your own page answers the buyer’s question more clearly | Create or improve a useful, well-structured page rather than copying the directory |
| A competitor is recommended for a specific use case | Whether your site explains your evidence and suitability for that use case | Add accurate proof, qualifications and details that help a buyer assess fit |
| Your page gets cited, but enquiries are not improving | Whether the destination page gives visitors a clear next step | Improve the page’s visual hierarchy, trust signals and enquiry flow |
These are investigation prompts, not guaranteed fixes. A missing mention may have several causes, and a website change may not produce a measurable AI result straight away. Track the action, date and affected page so future reports can distinguish work completed from outcomes observed.
If your findings point to a broader information or conversion problem, review the relevant website design and improvement service. AI visibility should not be separated from the visitor experience. Someone who follows a citation still needs a clear, credible page that helps them decide what to do.
Step 6: Set a sustainable tracking cadence
Choose a cadence your team can maintain. A monthly report is often easier to explain to a board than a stream of daily fluctuations, but the right interval depends on your team, platform access and the decisions you need to make. The important thing is to keep the prompt set and method consistent enough to compare periods.
A practical cycle looks like this:
- Establish a baseline. Run the agreed prompts across the chosen platforms. Save the answers, scores, citations and test conditions.
- Review patterns. Group findings by prompt type and platform. Look for repeated absences, inaccurate information, source patterns or strong recommendations for alternatives.
- Choose a small number of actions. Prioritise changes that improve the customer’s experience and make your business information clearer. Assign an owner and record the page or source involved.
- Repeat the test. Run the same prompts under comparable conditions. Mark any changes to the platform, prompt wording or process.
- Report the result with context. Show what changed, what did not, what the team changed on the website and what will be tested next.
Do not confuse a volatile answer with a meaningful trend. Entrepreneur describes the risk of drawing conclusions from a one-off AI visibility snapshot. Use repeated observations and report the method alongside the result. Read the article about AI answer volatility and visibility scoring.
For a small team, start with a spreadsheet and manual checks. A monitoring product may save time when you have enough prompts, platforms and reporting needs to justify it. Before paying, confirm which platforms and features it actually tracks, how it stores evidence, whether the prompts match your use case and whether its scores can be explained to your stakeholders. Do not buy a tool solely because it promises one headline score. If you want an automated approach, SearchFIT tracks AI search visibility across ChatGPT, Perplexity, Gemini, Grok, Claude and Google.
What belongs in the board update?
Keep the update short enough to support a decision. Include:
- Scope: platforms, prompt count, prompt groups, date range and testing method.
- Presence: mention rate by platform and prompt group.
- Recommendation: the number of responses in each score category.
- Attribution: the share of observed answers citing your own domain, where applicable, and the recurring external source types.
- Evidence: one or two representative answers, including the relevant citations.
- Work underway: the specific content or design changes made or planned.
- Limitations: variation in results, changes in method and anything the data cannot establish.
- Next decision: the action or resource required from the board, if any.
Avoid claiming that an AI mention caused a sale unless you have reliable attribution evidence. Website analytics, customer surveys and CRM records can add useful context, but each has limitations. Referral traffic may not represent every AI-influenced buyer, and people may not remember or disclose where they first heard about a business.
You can add an optional question to enquiry forms, such as ‘How did you first hear about us?’ Include AI search or named tools as answer choices only if they make sense for your audience. Make the question optional if answering it would add friction, and do not treat self-reported responses as a complete measurement of AI influence.
Common mistakes when measuring AI search visibility
Reporting one screenshot as a trend
A snapshot shows what one system returned in one session. Save it as evidence, but do not turn it into a claim about stable visibility. Repeat the test and show the observation period.
Mixing unlike prompts together
Brand validation prompts are more likely to include your name than generic discovery prompts because the prompt supplies it. Report prompt groups separately so the team can see whether you are being found without prompting.
Treating a mention as an endorsement
An answer can mention your brand neutrally or critically. Read the context and score the prominence separately from the mention rate.
Assuming rankings tell the whole story
A strong traditional search ranking does not guarantee that an AI-generated answer will mention your company. Search performance remains useful context, but it is a different signal. Compare the language and information on your pages with the questions in your prompt set.
Making a technical change without a customer reason
Adding schema, changing headings or publishing a file does not automatically lead to a recommendation. Make changes because they improve clarity, accuracy, accessibility or usability, then measure what happens. Avoid implying that any single implementation guarantees citations.
Chasing every absent prompt
Not every prompt is commercially relevant, and no business can expect to appear in every generated response. Prioritise prompts that match your customers, offer and market. A focused answer to a valuable question is more useful than a broad visibility score with no clear business meaning.
Changing the method without recording it
If the platform, session conditions, wording or scoring definitions change, note the change. Otherwise, a difference between periods may reflect the test rather than a change in how the business is represented.
Publishing pages for machines instead of people
A page written as a collection of keywords or answer fragments can damage trust and readability. Use clear structure to help real visitors first. Concise answers, useful comparisons, good typography and an obvious next step should work together as a considered page design.
How do you know if the measurement is useful?
A measurement process is useful if it helps your team make a better decision, not just produce a larger dashboard. After each reporting cycle, ask:
- Did the test reveal a repeatable pattern, or only a one-off answer?
- Are we visible for the buyer questions that matter most?
- Is the business description accurate where we appear?
- Which sources are shaping the answer, and are they current and credible?
- What change can we make that also helps a human visitor?
- What evidence will tell us whether the next action helped?
If you cannot answer those questions, simplify the test. Remove prompts that do not reflect a real customer decision. Keep the measures that show a useful distinction, and record limitations instead of filling gaps with assumptions.
The method should also be easy to explain to someone outside marketing. A board member should be able to see what was tested, what was observed, what action the team is taking and what the data cannot prove. That is more defensible than presenting a proprietary-looking score without showing how it was calculated.
Wrap-up: make AI visibility measurable, not mysterious
To measure AI search visibility, define the platforms and buyer questions that matter, build a stable prompt set, save repeated results and score mentions, recommendations and citations separately. Then inspect the pages and sources behind those results. Clear information design can make your business easier for visitors to understand and your content easier to navigate, but it cannot force an AI system to recommend you.
Use the findings to set a focused next step, then repeat the test under recorded conditions. If you want help identifying website and content issues that may affect how your business appears in AI search, start with DesignFIT’s free AI search audit.
Key takeaway
Track repeatable buyer prompts and separate brand mentions, recommendations and citations so your AI visibility report leads to a clear design or content decision.
Questions people ask
Can schema markup alone guarantee AI search visibility?
No. Schema can help clarify information when it accurately represents the visible page, but it cannot guarantee that an AI tool will mention or cite your business. Prioritise accurate content, clear page structure and a useful visitor experience, then test the results.
Why do we rank well on Google but not appear in ChatGPT or Perplexity?
Traditional search rankings and AI-generated answers are different outcomes, so a strong position in one does not guarantee inclusion in the other. Use your prompt tests to find which questions you are missing, then review whether your relevant pages clearly explain your offer, audience and evidence.
How often should I check AI search visibility?
Choose a repeatable schedule your team can maintain, such as a monthly reporting cycle, and record the dates and test conditions. If results vary between checks, report that variation rather than treating one answer as a trend.
Should I use a paid AI visibility tracking tool?
Start with manual checks if you are establishing a baseline and can manage the prompt set. Consider a paid tool when regular monitoring across platforms takes too much time, and verify its platform coverage, evidence storage and scoring method before relying on its report.